Live chat support metrics measure how fast, how well and how often your chat solves a shopper’s problem: first response time, wait time, chat duration, missed chats, chat CSAT, resolution in chat, transfers and concurrency. Once a bot or AI agent answers, add four more: containment, resolution, hand-off rate and the share resolved end to end, each with its own denominator.
Chat is the channel where the shopper is still on the page, so its numbers are about seconds and about whether the problem ended in the conversation. The moment a bot or AI agent answers first, most standard chat metrics quietly start measuring something else, the human queue behind the bot. This guide therefore separates human-chat metrics from AI-agent metrics.
It covers the chat-specific numbers for live chat. For CSAT, NPS and first contact resolution across all channels, see our service metrics guide, and for building the report, our ticket reporting guide.
What are live chat support metrics?
Live chat support metrics are times between two messages or counts divided by counts, which makes them easy to compute and easy to define inconsistently.
A live chat is a messaging widget where a shopper types a question and gets a reply in the same window. What it is and how to choose the software is covered in our website chat guide, so this page sticks to measuring it. If you run chat in Zendesk or on Shopify, the setup is in our Zendesk chat and Shopify chat guides; on PrestaShop, see PrestaShop chat.
How do you calculate each chat metric?
Write down what starts and stops each clock and which chats sit in the denominator before you report, because help desks define them differently and bot replies are often left out. The formulas below are our definitions; Zendesk’s wording for its chat metrics is quoted where it applies.
| Metric | Formula | What it tells you | Watch out for |
|---|---|---|---|
| First response time | Median time from the shopper’s first message (or joining the chat) to the first reply. Zendesk: “the time in seconds between the end user joining the chat and the agent’s first response” | Whether anyone is there when the shopper asks | Decide whether a bot or AI reply counts. Zendesk’s first reply time counts agent replies only |
| Average response time | Total time to reply to each shopper message in the chat, divided by the number of replies. Zendesk: average time for the agent to reply “during the chat session” | Whether the conversation keeps moving after the first reply | One slow mid-chat gap feels worse than a slow first reply; report the median per chat too |
| Wait time | Time in the queue before the first reply; if nobody replies, the time until the shopper left (Zendesk’s definition) | How long shoppers sit before help starts | Report it with the missed rate, otherwise short waits can hide shoppers who gave up |
| Chat duration | Time from the first to the last message (Zendesk) | How long a conversation takes | Long is not bad by itself; read it per contact reason. A duration target pushes agents to rush |
| Missed chat rate | Chats the shopper ended without any reply, divided by chats requested, times 100 | How often a shopper asks and nobody answers | Offline-form submissions are not missed chats; count them separately |
| Abandonment (queue dropout) rate | Shoppers who left the queue before being served, divided by shoppers who entered the queue, times 100 (LiveChat calls it queue dropout rate) | How many give up while waiting | Overlaps with missed chats; pick one definition per report |
| Chat CSAT | Good ratings divided by rated chats, times 100 (Zendesk rates Good or Bad; other tools use 1 to 5) | Whether shoppers felt helped | Always report the rated share next to it: rated chats divided by all chats |
| Resolution in chat | Chats solved in that conversation, where the shopper did not come back about it within X days on any channel, divided by all chats, times 100 | Whether chat ends problems or only starts them | You choose and state X, and you need ticket matching by customer |
| Transfer rate | Chats transferred to another agent or team, divided by served chats, times 100 (Zendesk counts transferred chats) | How often the first person cannot finish the job | An AI-to-human hand-off is not an agent-to-agent transfer; report it separately (see below) |
| Concurrency | Average active chats per agent per hour (Zendesk’s definition) | How many conversations each person is juggling | Higher concurrency raises capacity and slows each chat |
| Chats per agent | Chats handled per agent per day | Workload per person | Easy chats inflate it; compare per contact reason |
Average response time deserves its own line: a shopper waiting four minutes in the middle of a chat does not care that the first reply took twenty seconds. A chat duration target is the other trap, because a duration target tends to push agents to rush, so pair duration with resolution in chat, and read both per contact reason. For the all-channel resolution rate, our service metrics guide has the formula.
Which live chat KPIs should an online store track?
Start with five. Median first response time and missed chat rate tell you whether anyone is there. Resolution in chat tells you whether the problem ended. Chat CSAT with its rated share tells you whether the shopper felt helped. Once AI answers, add the share resolved end to end against the share handed over. Everything else is diagnostic.
Pair every speed number with a quality number: first response time with resolution in chat, concurrency with CSAT. Then report per contact reason, because WISMO, returns, address changes and product questions before purchase behave differently. Split pre-sale from after-sale chats as well. Pre-sale chats (size, fit, stock, delivery date) are judged on whether the shopper got a usable answer while still on the page. After-sale chats are judged on whether the order problem was solved.
Read both per hour of day, not only as a daily average: LiveChat’s retail data shows agents chatting about 2 hours 45 minutes a day against 11 hours 48 minutes globally, which it reads as support “more aligned with customer traffic patterns”. Peaks and gaps outside staffed hours are where the averages lie.
Dashboard averages also hide the cause: you need the conversations themselves to see why a chat went wrong. One Shopify Community feature request from a store owner asks for an export of inbox conversations for exactly that reason, so check that your chat tool lets you get them out before you rely on its dashboard.
What is a good live chat response time?
Answer while the shopper is still on the page. Published benchmarks put the first reply under a minute where chat is staffed: LiveChat reports 35 seconds globally and 55 seconds in retail. Queued chats wait far longer, and many shoppers give up: LiveChat puts the queue wait at 4 minutes 18 seconds and queue dropout at 27.4%.
| Benchmark | Figure | Source, year and sample | Caveat |
|---|---|---|---|
| First response time | 35 seconds globally; 55 seconds in retail | LiveChat Customer Service Report, last updated 2024, about 2 billion chats | LiveChat’s own customers, all industries |
| Chat duration | 8 minutes 25 seconds | LiveChat, 2024 | Cross-industry average |
| Queue wait | 4 minutes 18 seconds | LiveChat, 2024 | Queued chats only |
| Queue dropout | 27.4% | LiveChat, 2024 | Shoppers who left before being served |
| Chats per agent per day | 84.1 globally; 18.4 in retail | LiveChat, 2024 | Retail agents chat far fewer hours a day |
| Chat CSAT | 4.1 out of 5 | Comm100 benchmark report 2026, over 220 million chats, 18 industries | Vendor customers, all industries |
| Chat CSAT | 64.2% of rated chats; 6.7% of chats rated | LiveChat, 2024 | Tiny rated share, so read with care |
These are vendor figures from their own customers across industries, not e-commerce only, so use them as a sanity check, not a target. For first response versus resolution time across email and social, see our response time guide.
Satisfaction by channel is the other benchmark people ask for. An eDigital survey of 2,000 consumers, reported by Econsultancy in November 2013, found satisfaction of 73% for live chat, 61% for email and 44% for phone. It is old, so treat it as direction, not a current figure.
How many chats can one agent handle at once?
Set the limit by watching response time and CSAT as concurrency rises, not by a target number. Shopify puts an experienced agent at four to six chats at once, but each extra chat slows every chat: Call Centre Helper’s 2012 rule of thumb was that a webchat takes twice as long as a call when an agent runs three at once.
Concurrency is a capacity lever, not free speed. Use Zendesk’s definition, average active chats per agent per hour, and plot it against median response time and CSAT. At peaks, routing repeat order questions away from people protects concurrency for the chats that need one.
How do you measure a chatbot or AI agent in chat?
Count every chat the AI touches once, in one of three outcomes: resolved, handed off, or contained but not resolved, which includes shoppers who gave up.
Here is the trap: standard human-chat metrics stop measuring the AI. Zendesk’s documentation says that first reply time “is calculated exclusively based on agent replies”, and that most automated or bot actions are not counted.
So when a bot answers first, first response time measures the wait for a human after the bot. Report the AI’s first response separately, or report a time to first useful answer over all chats.
Microsoft Copilot Studio offers a neutral model with four outcomes: it records each session as Resolved, Escalated, Abandoned or Unengaged, and flags when a resolution was implied by the agent’s logic rather than confirmed by the user. The metrics we recommend are defined in the table below, and the one to compare with your team is resolved end to end, because it uses the same all-chats denominator.
After a hand-off, measure the human side as usual: the wait after the hand-off, the resolution, and whether the shopper had to repeat the order number. Gartner, reported by DestinationCRM in August 2026, says customers expect the option to reach a human agent when companies use AI.
Comm100’s 2026 report lists an “AI Chatbot-to-agent handoff CSAT” of 92.6%, a label it does not define on the page, so read it as a prompt to measure your own. How a chatbot differs from an AI agent is covered in AI agents.
Containment, resolution or hand-off: what does each count?
Containment minus resolution is the number to worry about: shoppers who left without help and without a person. The table shows what each term counts and how vendors label it.
| Term | Counts | Denominator | Misses | How a vendor labels it |
|---|---|---|---|---|
| Containment rate | Chats that ended without a hand-off | AI-handled chats | Whether the problem was solved; shoppers who gave up count as contained | Zendesk “Contained resolution”: handled to completion “without the customer requesting further assistance”, not passed by the LLM check |
| AI resolution rate | Solved, no human step, no re-contact in X days | AI-handled chats | Chats the AI never took on | Zendesk “Verified resolution” (passes an LLM check of the conversation); Intercom Fin “confirmed resolution” |
| Assumed resolution | Shopper left without asking for more help | AI-handled chats | Silent failures | Intercom Fin “assumed resolution”; Copilot Studio “implied” resolution |
| Hand-off rate | Chats passed to a person | AI-handled chats | What the AI did before passing | Zendesk “Assisted escalation” (the AI “contributed to the interaction before a human agent completed the resolution”); Copilot Studio “Escalated” |
| Resolved end to end | AI closed it, no human message or action | All chats (compare this one with your team) | Nothing, if re-contacts are matched | Our recommended headline |
These are each vendor’s own definitions, quoted to show how much the words differ, so define yours before comparing. Zendesk’s automated resolution tiers were introduced on 18 May 2026, and a messaging conversation ends 2 hours after the first message by default. Intercom counts a Fin resolution when the customer confirms the answer or exits without asking for more help.
Our practical check is to read a weekly sample of contained-but-unverified chats, because that is where missing resolutions and policy gaps hide. Then compare AI and team on the same denominator, all chats, with the same re-contact window. The all-channel version of this argument is in our deflection rate section, and AI-only conversations may be missing from standard help desk reports, as our reporting guide explains, so add AI and human chats together before you calculate.
Where does Engaige fit?
Engaige (that’s us) is the e-commerce-native AI support agent that plugs into the help desk you already run, Crisp included, resolves tickets end to end and keeps improving itself. Your reports stay in the tools you use today; these metrics count its resolved and handed-over chats. Engaige resolves rather than suggests: it reads the live order, catalogue and policy data, takes the action in your stack (refund, reshipment, address change), replies to the shopper and closes the ticket. Keep your helpdesk. Replace the AI.
The angle for this article is resolved versus handed over. Count what the agent resolved end to end, closed with no human message or action, apart from what it handed back to your team, on the same all-chats denominator as your team. A hand-off is not a resolution, and an assisted chat is not an automated one.
At MR MARVIS, a Shopify Plus brand with over 120,000 questions a year, Engaige is resolving over 60% of the conversations it’s involved in. Otrium resolves 60% of 120,000 annual tickets end to end.
With Engaige, we are able to automatically resolve 60% of the 120,000 support tickets that we receive annually.
Otrium’s case describes the hand-off side too: when a ticket falls outside the policies you set, Oliver, its agent built with Engaige, hands it to a human agent so nothing falls through the cracks, and Engaige AI learns from the hand-offs under your supervision.
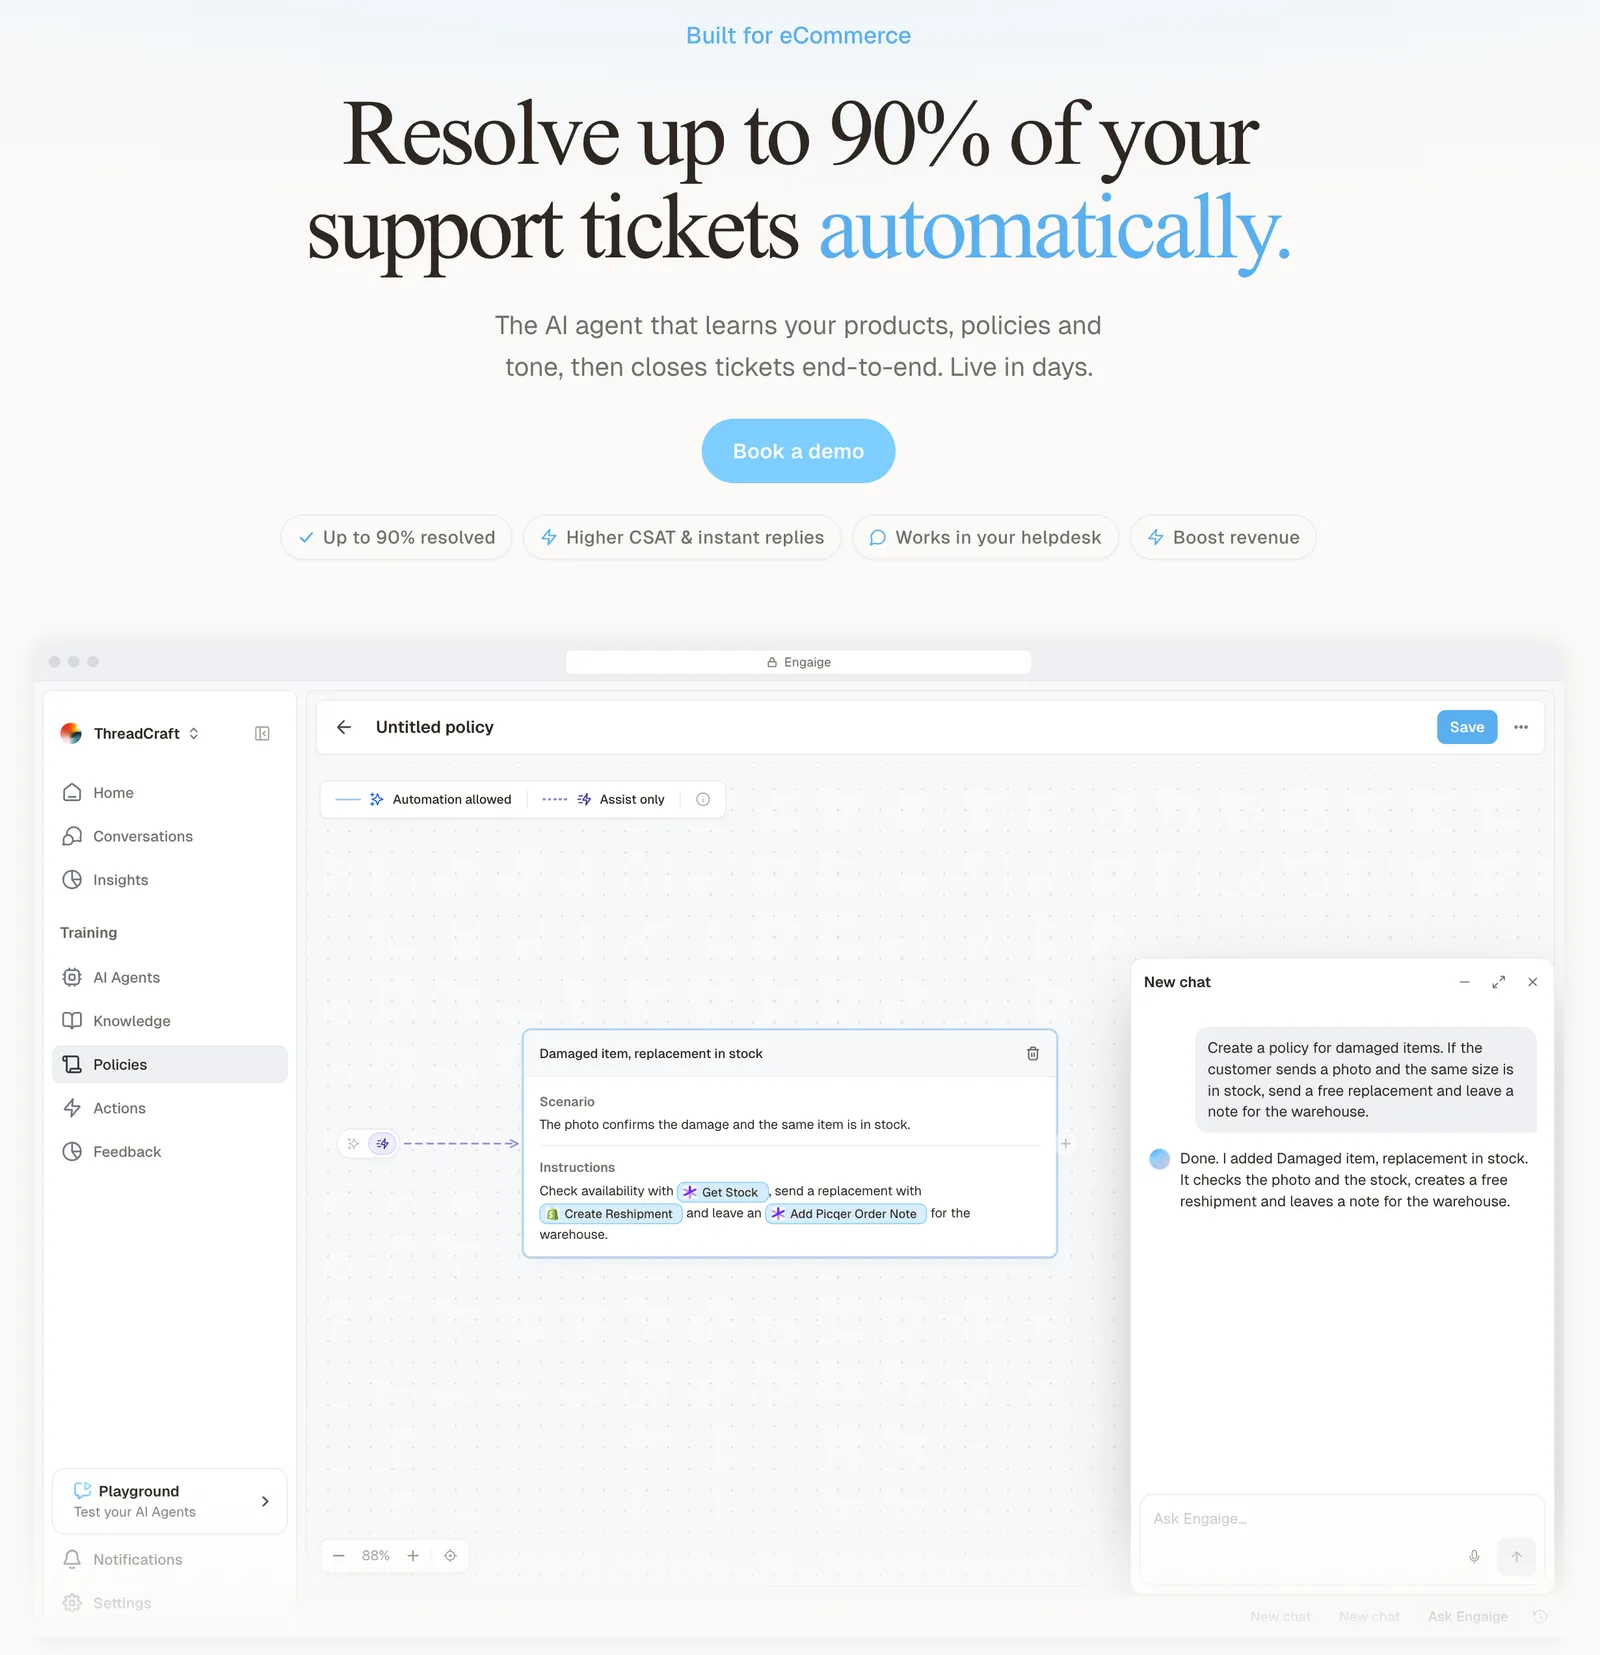
You go live in Agent Assist in hours, where nothing closes without a human. Engaige AI compares what your team said with what the agent suggested, learns from the difference, and improves itself, under your supervision: you approve the changes. Ticket types switch to autonomous one at a time, autonomous in about a week, and Engaige automates up to 90% of supported tickets. Autonomous from day one is also supported.
Once autonomous, Engaige AI surfaces emerging trends and the tickets the agent hands back to a human, and proposes policy changes you approve. So the hand-off rate is not only a number to report.
Hello Potential New Client
What would you like to get done today?
Could you analyse this week's conversations and show me some automation opportunities?
Ask Engaige…
Searched and found 4 contact reasons · 2.4s
Your agent resolved 426 of 512 conversations. 86 were handed over, and one contact reason accounts for most of them.
Searched and found 1 policy · 1.6s
Delivery status hands over whenever tracking is older than 24 hours, which is 40 of those 46.
Editing Delivery status · 1.9s
Done. It now handles stale tracking itself. Those 40 a week stay with your agent.
What were the reasons for handover, and how can we improve?
Fix it.
Reply…
Engaige AI shows the reasoning and which policy it applied, and you control what the agent may do alone. Engaige is built for e-commerce and deepest on Shopify. The full picture is in our live chat hub; for the chat side of a help desk, see Crisp chat, or see your own resolved and handed-over split in a demo. For order-status chats, see WISMO.
Frequently asked questions
What are the most important live chat metrics?
Median first response time, missed chat rate, resolution in chat, chat CSAT with its rated share and, once AI answers, the share resolved end to end against the share handed over. Everything else is diagnostic.
How do you calculate first response time in live chat?
Take the time from the shopper’s first message to the first reply and report the median. State whether bot replies count, because Zendesk’s first reply time counts agent replies only.
What is a good live chat response time?
Under a minute where chat is staffed; the benchmarks and their caveats are in the response time section above.
What is the difference between a missed chat and an abandoned chat?
A missed chat is one the shopper ended with no reply at all. An abandoned chat, or queue dropout, is a shopper who left the queue before being served. Pick one definition per report.
How many chats can an agent handle at once?
Shopify says four to six for an experienced agent, and Call Centre Helper’s 2012 rule of thumb was that a webchat takes twice as long as a call when an agent runs three at once. Watch CSAT as concurrency rises.
What is the difference between containment rate and resolution rate?
Containment is the share of chats that ended without a hand-off to a person. Resolution is the share where the problem was actually solved and the shopper did not come back about it within X days, a window you choose and state. Containment minus resolution is the shoppers who left without help. The table in the containment, resolution and hand-off section sets out the denominators.
How should you count chats an AI agent resolves?
Count chats resolved end to end, with no human message or action, over all chats, apart from hand-offs, using the same denominator and re-contact window as your team. At MR MARVIS, Engaige is resolving over 60% of the conversations it’s involved in, and Otrium resolves 60% of 120,000 annual tickets end to end.
Does Engaige replace my chat or help desk reports?
Keep your helpdesk. Replace the AI. Engaige works alongside the help desk or Crisp inbox you run, and your reports stay where they are. Engaige AI learns from hand-offs and trends and proposes policy changes you approve.